One image in, one animation out
A 27B vision model gets a design brief as a single PNG and has to build it as a canvas animation. Six files of the same base model, same cards, same seeds. Every tile below is a model's unedited output.
Title-sequence card, seed 2. Top row: bf16 original, Q4_K_M, Q3_K_M. Bottom row: Opti, Bonsai 2 PQ2_0, Bonsai 2 PTQ1_0. Each video opens with 2.5 s of the brief card; each label carries that page's checklist score out of 17. A dark tile is a page that threw a JavaScript error.
The three brief cards
The only text prompt is: "Build what the attached brief specifies. Reply with one complete, self-contained HTML file in a single html code block." Everything else is on the card, much of it drawn rather than written: swatches, a wireframe, pip rows for counts, a timeline strip in a deliberately unnatural order, a storyboard that is not in play order, and strings that cannot be guessed.
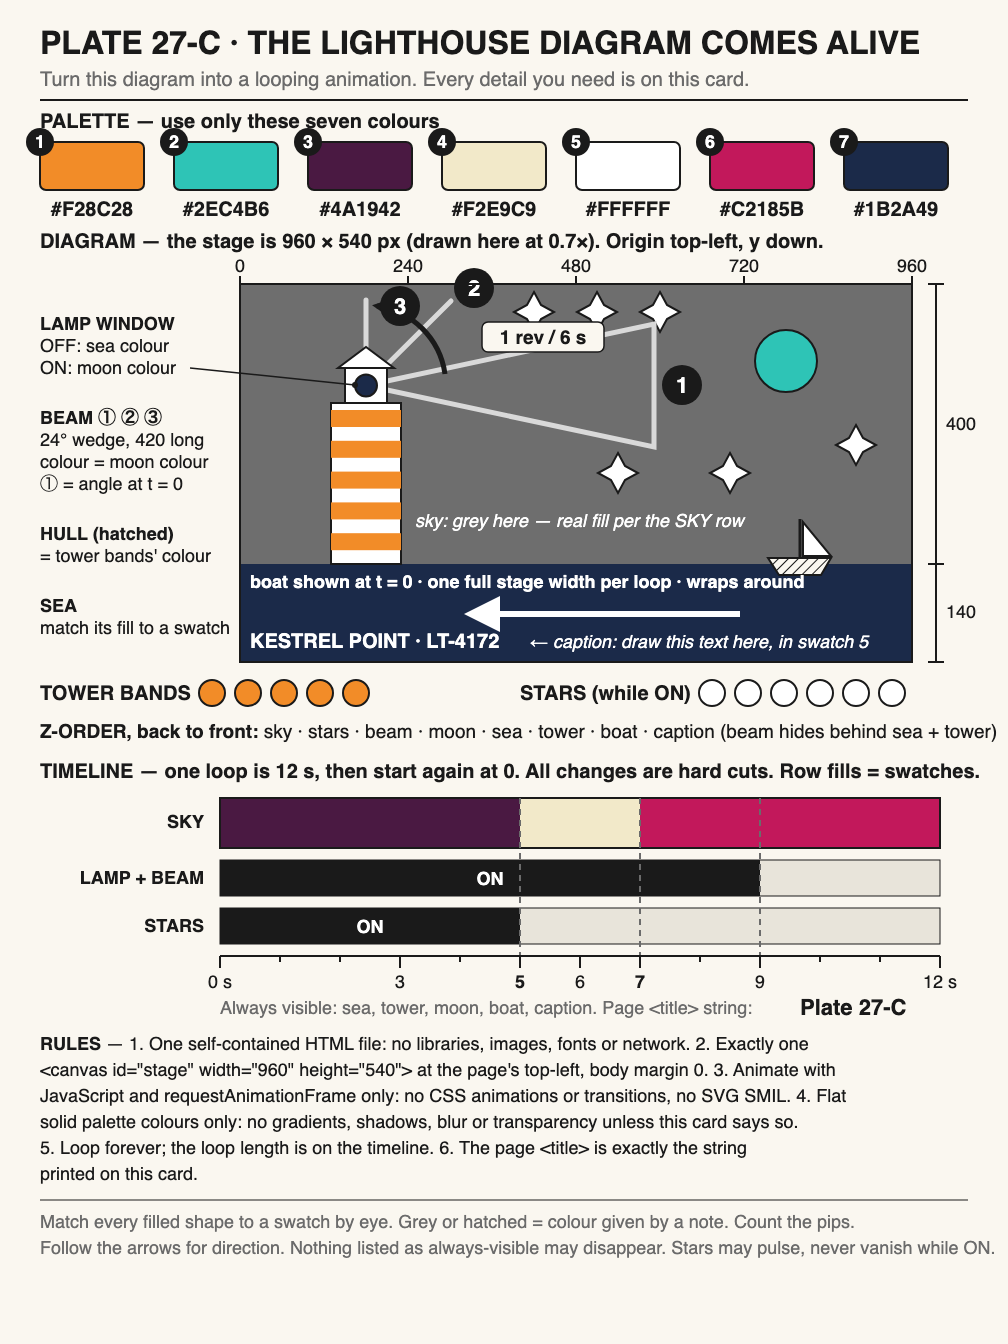
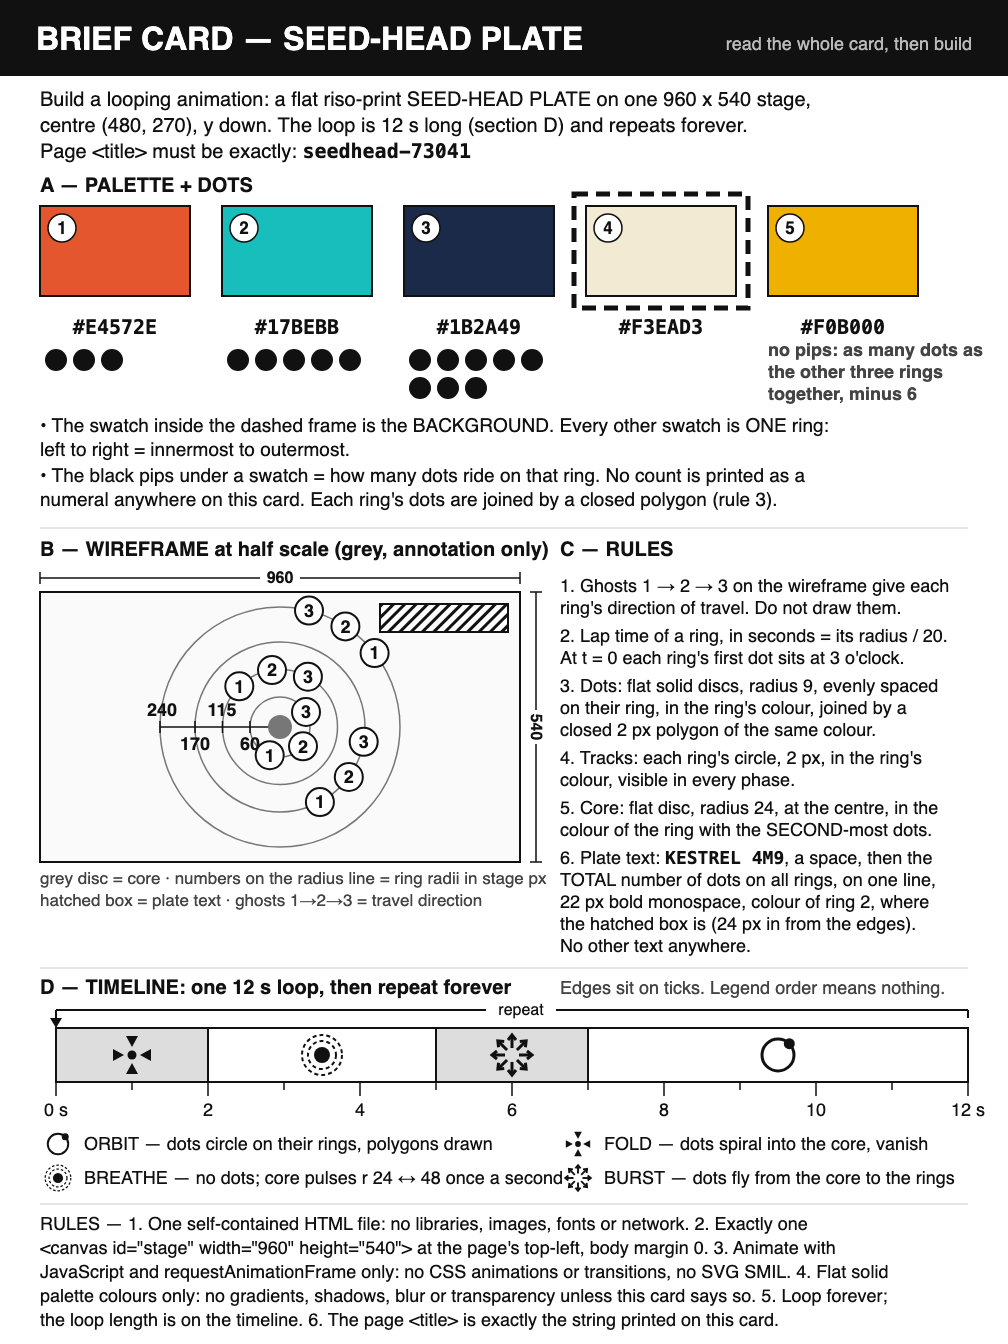
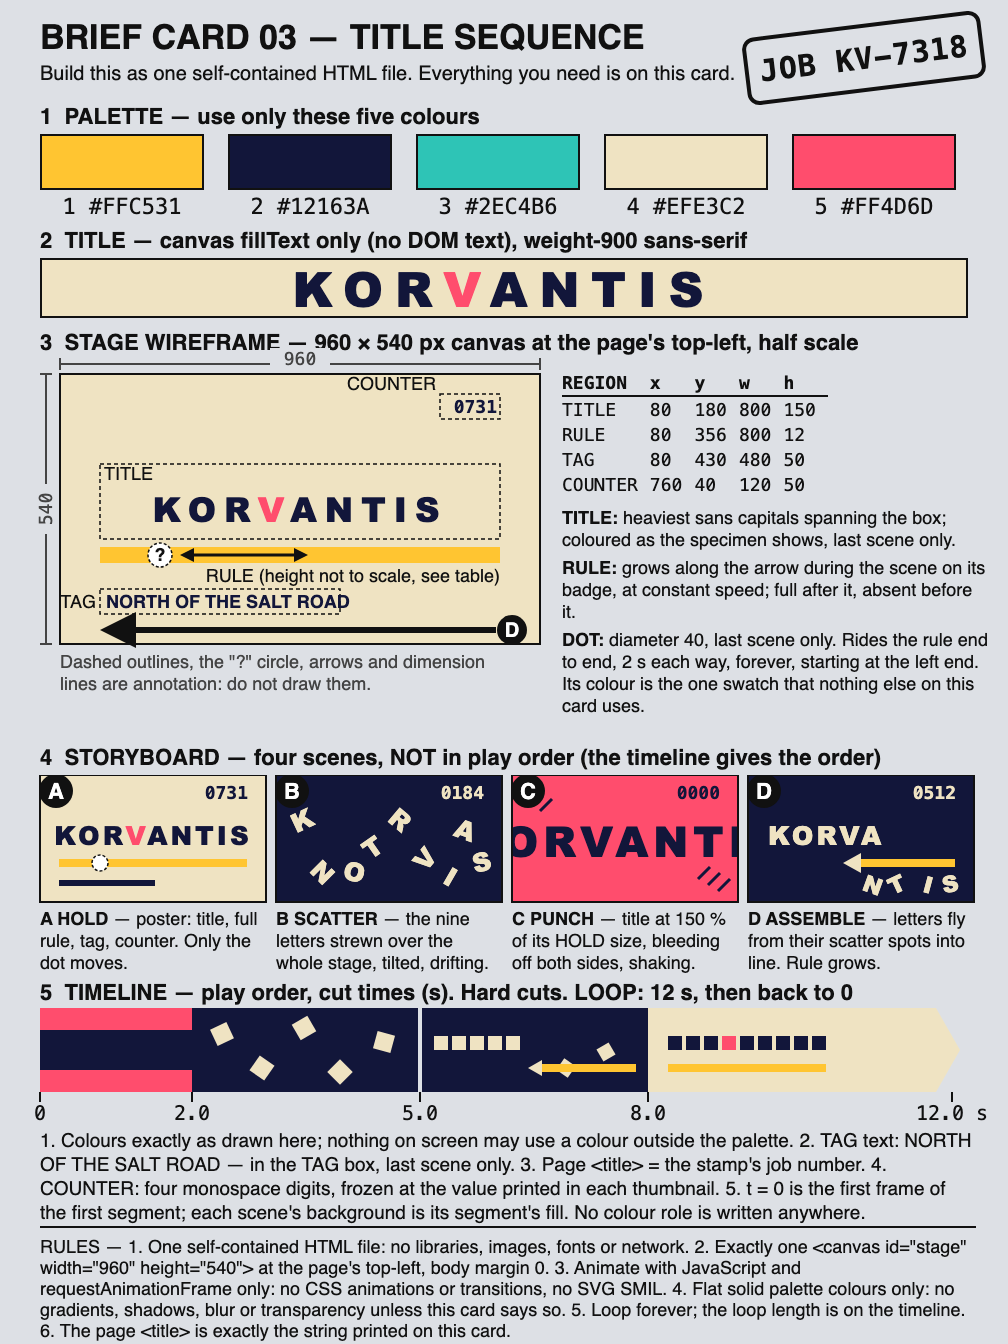
Results
7 pages per file (3 cards × 2 seeds, plus a third seed on the ring card), 17 checks per page. Every page counts, crashes included, nothing regenerated or dropped. Columns are the same card and seed for every file.
| File | Size | Page scores (of 17) | Mean | Pages without a JS error |
|---|---|---|---|---|
| bf16 original | 53.8 GB | 13 16 16 10 15 14 13 | 13.9 | 7 / 7 |
| llama.cpp Q4_K_M | 16.6 GB | 14 14 9 13 16 14 16 | 13.7 | 7 / 7 |
| llama.cpp Q3_K_M | 13.3 GB | 9 14 8 16 17 14 13 | 13.0 | 7 / 7 |
| Opti | 12.0 GB | 13 14 3 14 9 13 14 | 11.4 | 6 / 7 |
| Ternary Bonsai 2 PQ2_0 | 7.2 GB | 12 4 6 4 7 4 4 | 5.9 | 3 / 7 |
| Ternary Bonsai 2 PTQ1_0 | 5.9 GB | 8 4 4 3 0 6 10 | 5.0 | 3 / 7 |
- The unit is the page, not the check: checks on one page rise and fall together (one JS error takes out 14 at once).
- Opti is within 2 checks of Q4_K_M on 5 of the 7 pages, at 72% of its file size. Its lower mean comes from two pages on the ring card: one crashed on a JavaScript scoping bug, one drew wrong dot counts.
- A paired permutation test on the seven page differences does not resolve Opti from any other Qwen file (p = 0.13 vs Q4_K_M, 0.34 vs bf16, 0.38 vs Q3_K_M). Seven pages cannot prove the files equal; run-to-run spread is larger than the gap between them.
- Bonsai's gap is resolved: 8 of its 14 pages died on JavaScript errors, and about half its replies ran out the token budget. PrismML reports strong results on their own thinking-mode suite, which was not reproduced here. This is one task.
- No file, including bf16, reads direction from a diagram: rule grows right-to-left 0 of 8, beam counter-clockwise 1 of 8, ring spin 2 of 12, boat toward smaller x 2 of 8 (Qwen files).
All seven runs
Scores under each video, in order: bf16 · Q4_K_M · Q3_K_M · Opti · Bonsai PQ2_0 · Bonsai PTQ1_0.
How it was run and graded
- Base model Qwen3.8-27B. Same prompt, sampling (temperature 0.6, top-p 0.95, top-k 20), seeds and token budgets (6k thinking, 8k answer) for every file, thinking on,
llama-server. The four Qwen files share one vision projector; Bonsai runs in PrismML's own llama.cpp fork with the projector they ship. Opti here is an unreleased build (llama.cpp 2/3/4-bit layers plus a small learned corrector network), not the file currently on Hugging Face. - Every reply is opened in headless Chromium on a fake clock stepped 40 ms per frame, so frame k is exactly t = k/25 s on any CPU. That is why the tiles run in lockstep.
- Each card has 17 checks (5 shared rules + 12 card-specific) fixed before any model ran: pixel sampling at exact times, blob counts, angular-velocity ratios, a
fillTexthook for on-canvas strings. A hand-written reference page per card scores 17/17, a blank page 4/17, and each mutant (wrong count, reversed direction, wrong phase order…) fails only the check it targets. - Every crashed page was re-opened in a plain browser with no fake clock and no hooks; each throws the same error there, so the crashes are in the models' code, not the harness. One Bonsai reply never produced a page inside the answer budget and scores 0.
- One grading fix was made after the first pass: two files (Opti, Q3_K_M) drew a correct 960×540 canvas and CSS-scaled it to half size because the wireframe says "half scale". The grader now captures the canvas at its drawn resolution and charges the size rule once. bf16 and Q4_K_M were unaffected.
n is small. This is a demo with a rough score, not a benchmark.